
How to spend fewer AI tokens: 42% less per message in the main chat of Claude Code
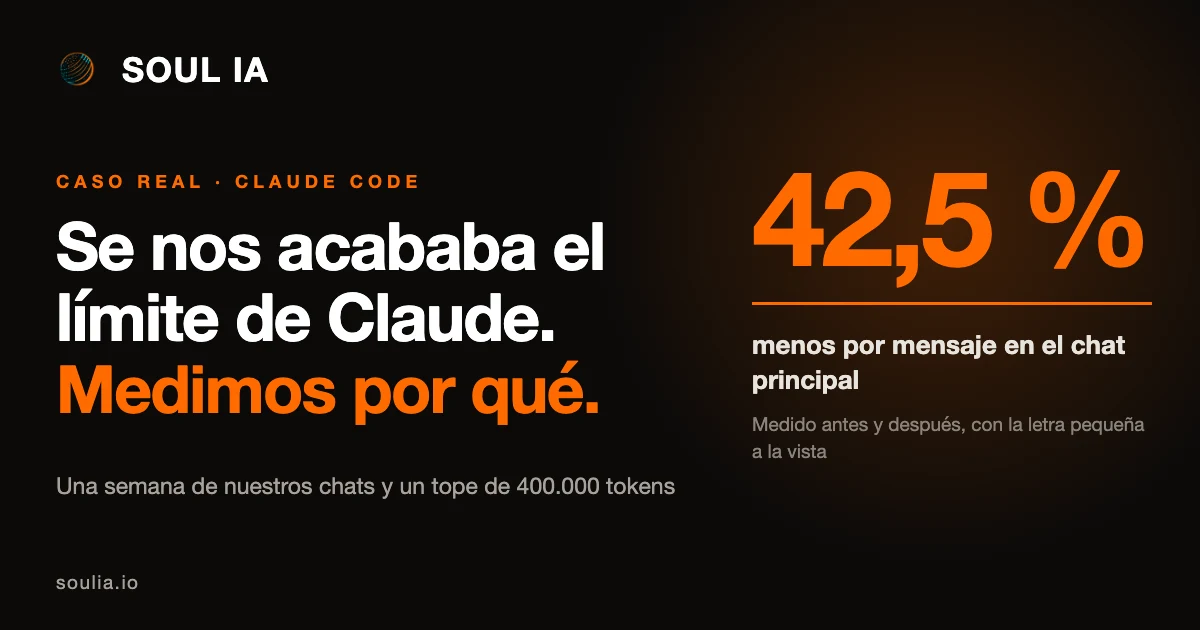
Every time you send Claude Code a message, it rereads the whole conversation. Even a one-line message, if the chat has been open all day. That is why a long conversation burns so many tokens, and why the biggest lever for spending less is not writing less but deciding when a conversation ends. In this article we explain what we measured in our own chats, what we changed and how much it saved: 42.5% less per message in the main chat and 30.6% less counting every chat, measured before and after and with no A/B test. With the table, the cost of compacting and everything we still do not know.
This is not a generic guide or a benchmark: it is a specific study of our own, run on real Claude Code use at Soul IA over one week (47 chats, more than 4,000 messages). The figures are the ones we measured, and the fine print sits right next to them.
71% of the spend came from endless chats
Share of spend by the tokens each message carries. Our own measurement: 47 chats and more than 4,000 messages. The fine print is further down.
The step by step, in six moves
- We saw the symptom. On October 2 we hit 77% of our plan's five-hour window, without knowing why.
- We built our own meter. A script that reads Claude Code's local transcripts and works out what each message costs.
- We measured one week, touching nothing. From September 29 to October 5: 47 chats and 4,066 messages, split by the size of the conversation each message carried.
- We found where it went. 71% of the main chat's spend came from messages with more than 400,000 tokens of conversation behind them.
- We set a cap. Claude summarises the conversation when it reaches 400,000 tokens instead of waiting for almost a million, and we built a system around it so the summary does not lose what matters.
- We checked it two ways. A simulation over the real compactions and a before-and-after comparison. And we wrote down everything we do not know.
Why a long conversation burns so many tokens
A token is a piece of text, a word or part of a word, that the model reads or writes. Usage is measured in tokens, and what you do not see at a glance is that the model does not remember the conversation: it is sent the whole thing again with every request.
The official Claude Code documentation says it plainly: cost grows with the size of the context, and a one-line question in a session that has been open all day is billed for the entire conversation. Prompt caching makes that rereading cheaper, but it does not remove it. And if you step away for longer than the cache lasts (one hour on a subscription), the first message when you come back reprocesses everything again.
There is also a fixed cost up front. In our setup, a new chat already started at about 71,000 tokens (tools, skills, memory and system prompt) before we typed a single word. Measured on 5 October; every setup is different.
What we measured before touching anything
On 2 October we hit 77% of our plan's five-hour window by launching many tasks at once. That is when we decided to stop guessing and measure. We built our own meter that reads the local transcripts and, on 5 October, analysed the week from 29 September to 5 October: 47 chats and 4,066 messages in the main thread.
One clarification that matters for everything that follows: we measure in units, not in raw tokens or euros. A unit is millions of tokens weighted by price (reading from cache weighs 0.1; writing to cache, 1.25 or 2; the model's output, 5). It is an estimated quota, useful for comparing our chats with each other, not an invoice.
This is how the main thread's spend was split by the size of the conversation each message carried:
| Message context | Share of spend | Messages |
|---|---|---|
| up to 150,000 tokens | 4.9% | 467 |
| 150,000 to 250,000 | 8.2% | 679 |
| 250,000 to 400,000 | 15.8% | 833 |
| 400,000 to 600,000 | 29.6% | 958 |
| over 600,000 | 41.6% | 1,129 |
Messages with more than 400,000 tokens of conversation behind them added up to 71% of the main thread's spend (55% if you also count subagents). And not because we wrote a lot: in that spend, 54.6% is rereading the cache, 35.0% is writing to the cache and only 10.4% is what the model writes.
There was another hole: going back to a chat that had been idle for more than an hour. That week it happened 71 times with more than 100,000 tokens rewritten into the cache, and it took 21% of the spend. The worst case was a single message that rewrote 850,000 tokens.
Subagents (the helpers Claude Code launches for separate tasks) were another 34% of that week's total spend. They started clean, but each one builds up its own context as it works.
What we changed: a cap on the context, not less work
By default, Claude Code with a 1 million window compacts (summarises the old conversation) at around 967,000 tokens. We set the autoCompactWindow option to 400,000. Since Claude Code leaves a buffer of 33,000, in practice it compacts at around 367,000. After compacting, the chat goes back to about 116,000 tokens (measured median) and carries on.
Two clarifications so that nobody repeats a mistake we made. First: 400,000 is not an Anthropic recommendation. On 7 October we treated it as recommended based on a summary we had not checked against the source; on the 16th we corrected it. The documentation leaves the window on automatic and does not suggest any value: 400,000 is our own cost decision. Second: it is applied from the settings (settings.json), which Claude Code reads when a session starts; chats that were already open do not pick it up on their own.
Compacting carries a real risk: the summary loses detail. The official documentation admits it, and the community reports cases of rules being forgotten after a compaction. That is why we did not change just the number. We built a system around it that does not spend model: instructions so that the summary is 12,000 characters at most with fixed sections (request and rules, decisions, findings, status and next step), a mechanical log that recovers the latest messages, the files touched and the commands from the transcript itself, and a warning when a chat has compacted several times. The full conversation stays on disk in case a detail has to be looked up.
How much it saves: the table
Using the real compactions from the 8.6 days with the cap (from 7 October at 9:30 to 15 October at 22:45: 66 chats, 12,594 main-thread messages and 170 compactions), we simulated what the same sequence of messages would have cost with other caps. There are two reasonable ways to model the moment of compaction and we do not know which is closer to reality, so we calculated both and give the range.
| Cap | Compactions per active day | Waiting for compactions, minutes per day | Total spend versus 400,000 | Saving versus no cap |
|---|---|---|---|---|
| 300,000 | 56 to 60 | 46 to 50 | 6.3% to 6.6% less | 34.8% to 35.7% |
| 400,000 (ours) | 32 to 34 | 27 to 29 | 0% | 30.4% to 31.2% |
| 500,000 | 22 to 23 | 19 | 7.1% to 7.9% more | 25.5% to 25.7% |
| 600,000 | 16 to 17 | 14 | 15.3% to 16.2% more | 19.8% to 20.0% |
| 800,000 | 10.6 to 10.8 | 9 | 30.3% to 32.0% more | 9.1% to 9.3% |
| No cap (1 million) | 7 | 6 | 43.7% to 45.3% more | 0% |
An active day is a day with compactions (there were 5 in the window). The waiting time comes from 50 seconds per compaction, the average we measured.
The reading: with no cap, the same sequence of messages would have cost 44% more. With the 400,000 cap we save 31% of total spend and 34 to 35% of the main thread (in subagents, between 14 and 15%). Raising the cap to 500,000 costs 7 to 9% more. Lowering it to 300,000 saves only 6 or 7% more, but almost doubles the compactions, and every compaction is a chance to lose detail. That is why we chose 400,000: a reasonable compromise, not a proven optimum.
We repeated the calculation on 20 October on the same data and got the same result.
What the before and after measured
The simulation calculates what would have happened. To see what did happen, we compared the week before (29 September to 7 October) with the 8.6 days with the cap:
- The average main-thread message went from 0.0803 to 0.0462 units: 42.5% less, with the average context falling from 459,000 to 240,000 tokens.
- Counting all messages (subagents too), from 0.0635 to 0.0441: 30.6% less.
- Per day, total spend barely changed (from 91.5 to 87.4 units, 4% less) and messages rose 38% (from 1,440 to 1,982 a day).
That last line is the one that matters: with almost the same daily spend, we sent quite a few more messages. But be careful with what it does not say.
What we do not know, and why we do not use a prettier number
There are rounder, flashier numbers. This is the one that holds up, and this is its fine print:
- It is not an A/B test. On 7 October it was not only the cap that changed: so did the split of work, the use of subagents and the compaction instructions. The before and after does not separate causes, and the gap between the 42.5% measured and the 34% to 35% simulated for the main thread may be a mix of tasks. We have designed an A/B test of the cap (400,000 against 600,000, randomised at each decision point), but it is a draft and we have not switched it on.
- We did not measure quality. Not finished tasks, not errors, not real waiting times between caps. A cheaper message is not better work. The 38% more messages is not finished work: some of it may be rereading after compacting.
- Compacting costs. The compaction itself is between 5.2% and 5.5% of the simulated spend. After a compaction under the cap, the chat rereads on average 1.16 already-read files in the next 40 calls (against 0.33 at control points without compaction), about 3,000 extra tokens. And every compaction is about 50 seconds of waiting.
- One person, 8.6 days. Only 32 of the 66 chats ever compacted, and the 10 with the most compactions add up to 78%. Do not extrapolate it to your team without measuring your own.
- Estimated quota, not tokens or euros. The units are an estimator of ours, calibrated against exact usage readings, but still an estimator.
If someone promises you "90% fewer tokens", ask by what measure, on which chats and what happened to the work.
Did we fix it? How far we got and how far we did not
The honest answer: we fixed one part, and another is still open.
- What we did fix: each message costs quite a lot less. 42.5% less in the main chat and 30.6% counting every chat; the simulation points to 31%.
- What the cap does not fix on its own: total spend per day barely moved (4%). What changed is that on the same spend we sent 38% more messages. If your goal is to spend less overall, the cap is not enough. If it is to hit the limit less often, you need to check that the extra 38% is useful work, and we have not measured that yet.
- What is still open: subagents were 34% of the spend and the cap only lowers them by 14 to 15%. Going back to a chat that has been idle for over an hour (21% of that week's spend) is not something the cap addresses, and we have not measured it separately.
- What it would take to call it closed: switch on the A/B test of the cap and measure whether the work comes out just as good.
Other habits the official documentation recommends
We have not measured these separately and we attribute no percentage to them; they are the ones described on the official Claude Code costs page:
- Clear between unrelated tasks with /clear. It is free, and old context is paid for in every following message.
- Compact with a focus (/compact followed by what to keep) at natural breaks between tasks, rather than waiting for the automatic one in the middle of one.
- Choose the model for the task. Sonnet for most things and Opus for what genuinely needs it; simple subagents on a smaller model.
- Keep CLAUDE.md short (the guide recommends under 200 lines) and move to skills whatever is only needed sometimes.
- Turn off the MCP servers you do not use and delegate huge outputs (tests, logs) to subagents.
- Ask for specific things. "Add validation to the login in auth.ts" costs less than "improve the code".
- Stop early if it goes wrong (Escape and /rewind) and use plan mode for anything complex.
Frequently asked questions
What is a token?
A piece of text, a word or part of a word, that the model reads or writes. Use of a language model is measured in tokens, input and output.
Why does a long conversation use more tokens?
Because on every request Claude Code sends the whole conversation. With prompt caching that rereading is cheaper, but it still counts against your usage. And after a pause longer than the cache, the first message reprocesses everything.
Does compacting the conversation lose information?
Yes, it loses detail: literal outputs, instructions given only in words, nuance. It does not lose what sits in files that reload on their own (CLAUDE.md, memory) or the transcript, which stays on disk. What matters is best kept in those files and not only in the conversation.
How much can you save?
In our chats, 42.5% less per message in the main chat and 30.6% less counting every chat, measured comparing before and after; the simulation against no cap gives 31%. With no A/B test and no quality measure. Your figure will depend on how you work; measure your own first.
Does it apply to ChatGPT or other assistants?
The underlying mechanics, that every turn reprocesses the history, are those of any language model used through an API. But our figures are for Claude Code and we do not carry them over to other tools.
/clear or /compact?
/clear starts from zero and costs nothing. /compact keeps a summary, but it reads the whole conversation first, so compacting a huge context is itself a big request.
The rule we take away
AI spend has a component you cannot see on the dashboard and that is fixed with order: how much each conversation carries and when it ends. We measured it before touching anything, and that is what separates an adjustment that saves from one that only looks like it saves. If your company already uses AI every day and nobody knows where the spend comes from, we can look at your case.
If your team uses AI every day, a big share of your spend may be coming from endless conversations without you seeing it. We do it with you: we measure your real use, tell you how much goes on chats that never close, and set up the cap and the system that avoids losing context when it summarises. Every week you carry on as you are, you pay for the AI to reread the same thing again.
Written by
Jorge Marín Pérez · Founder of Soul IA
I help SMEs automate their customer service and processes with AI, from Málaga. What I write here comes from what we build every week for real businesses.
Want to know what you could automate in your business?
Talk to Soul IA